Permanent move
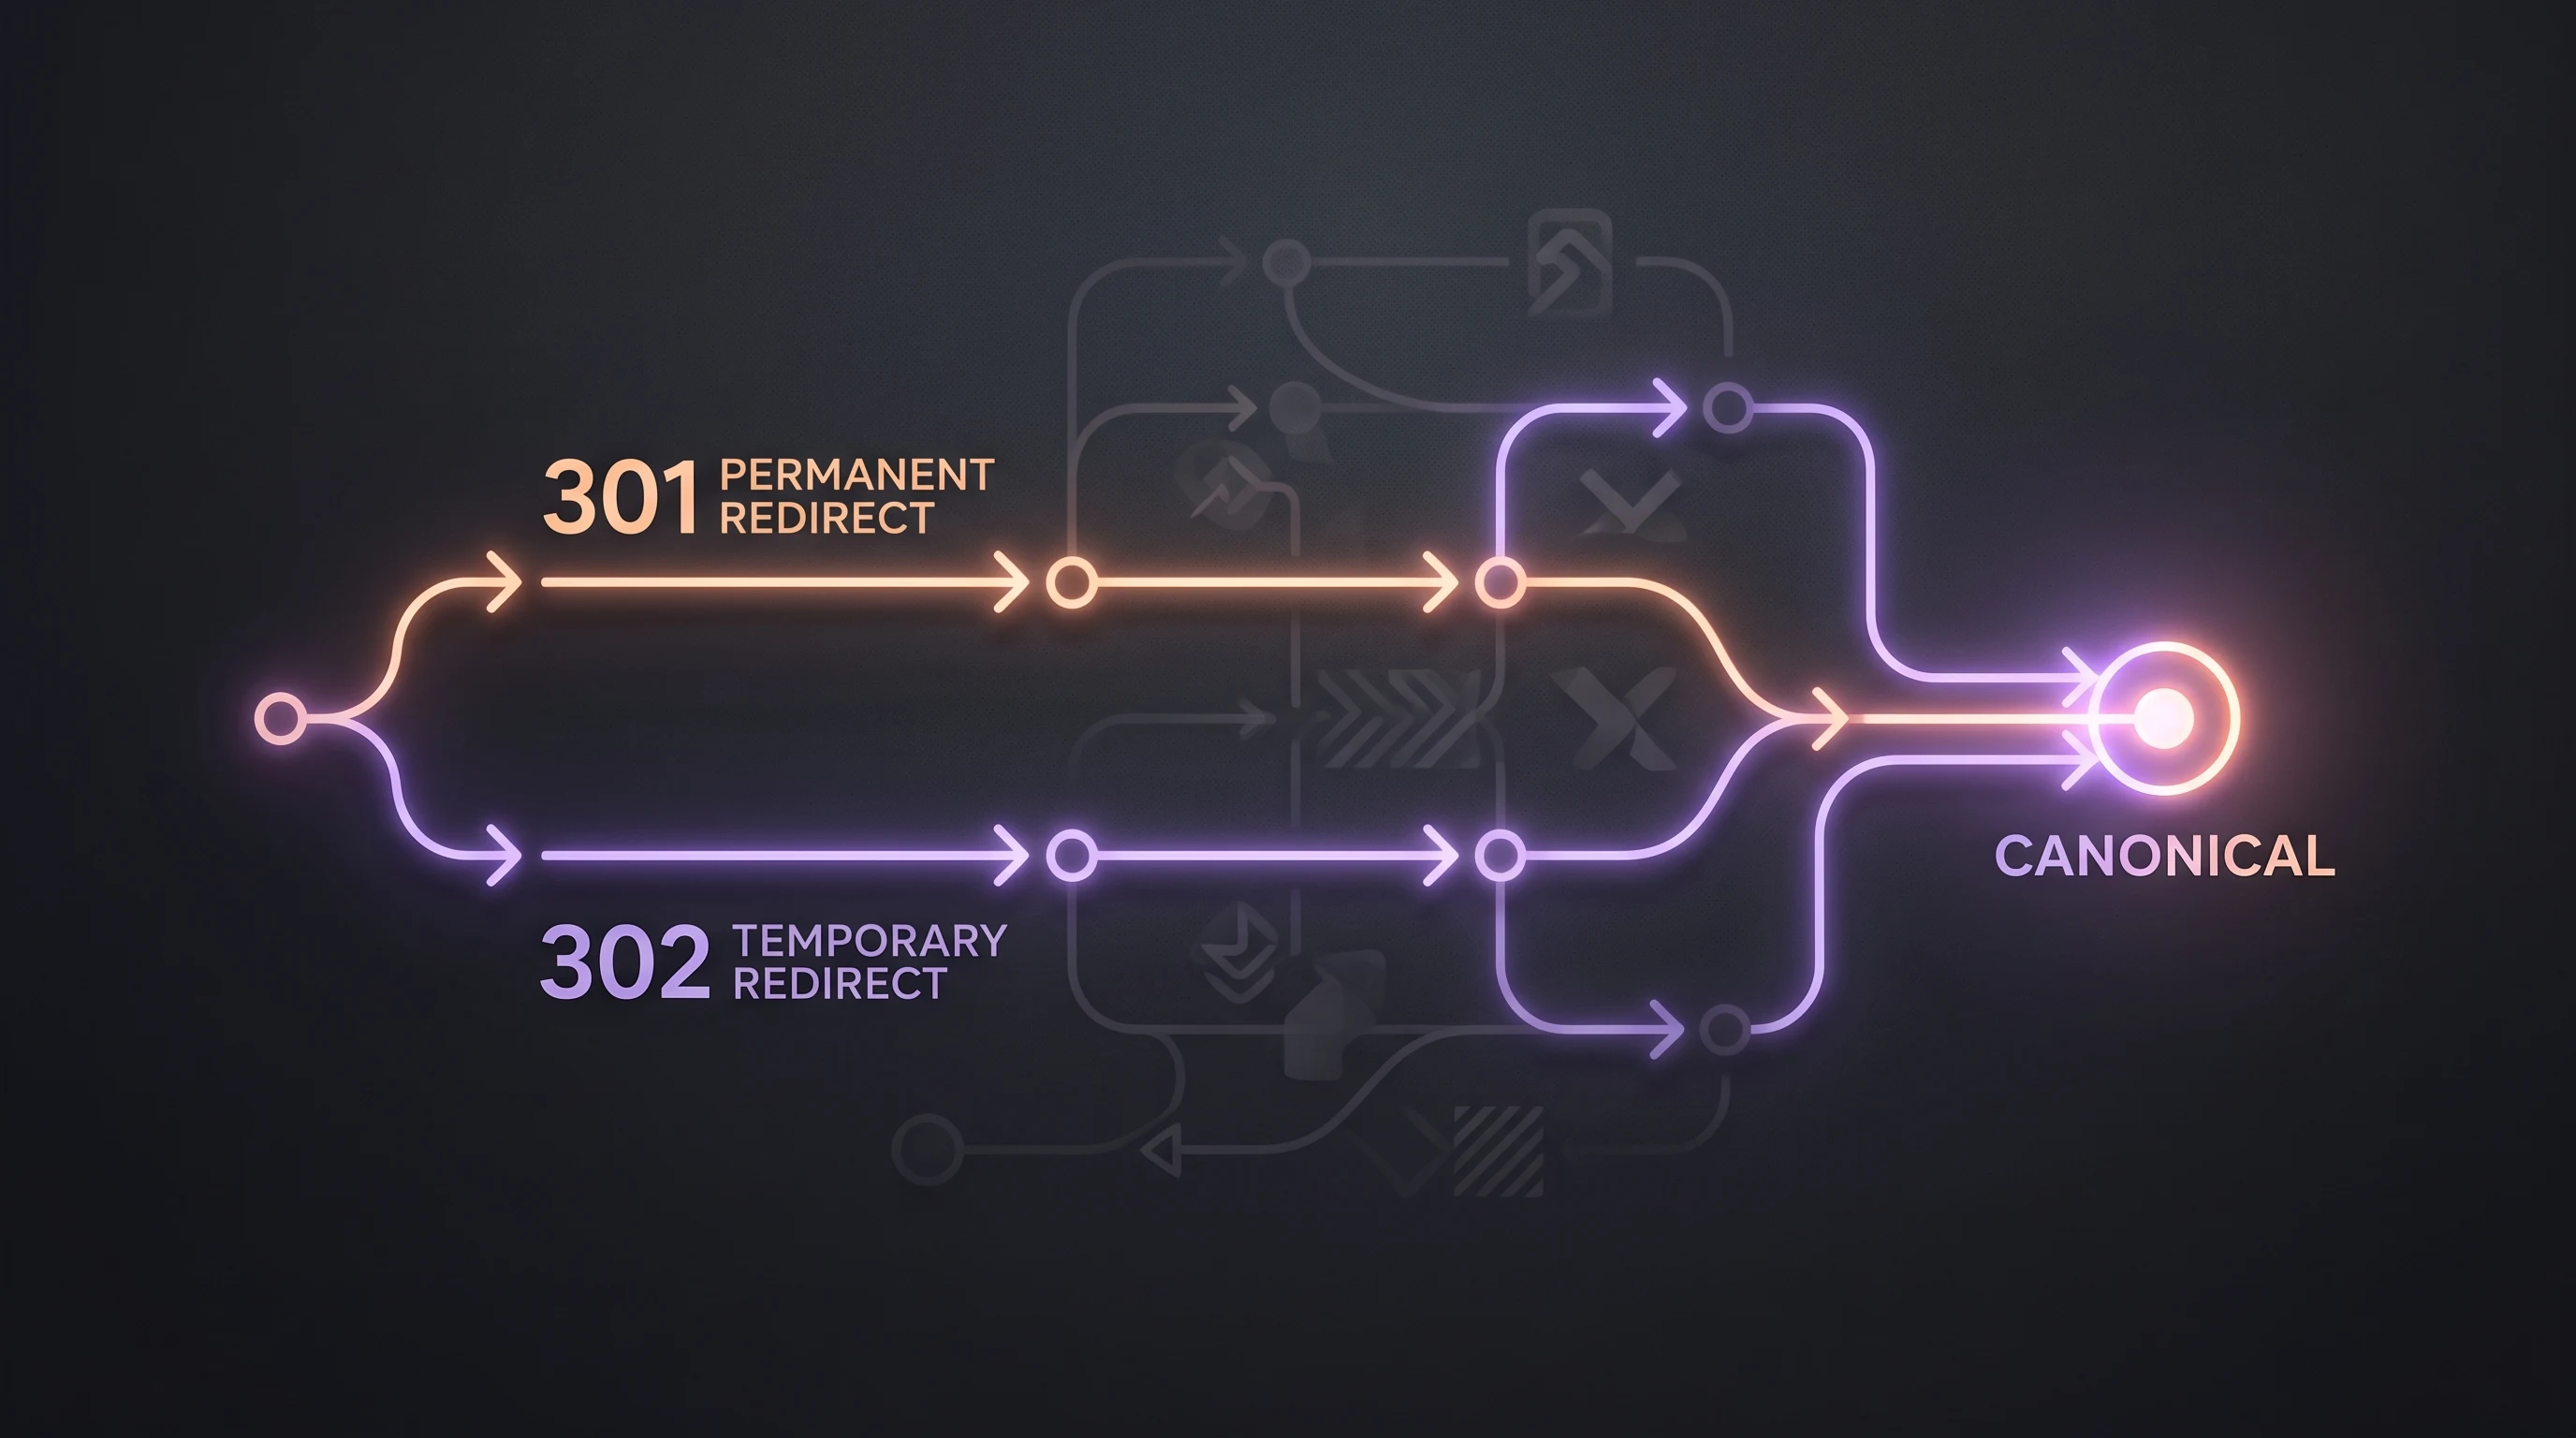
Google treats permanent server-side redirects as a signal that the target should become canonical.
Technical SEO · Redirects · Site migrations
Redirects are not a cleanup rule to add after a migration. They are part of the URL-state contract: status semantics, destination equivalence, canonical signals, internal links and release validation must agree before old URLs are retired.
The short answer
Use 301 or 308 when an old URL has permanently moved to a real equivalent; use 302 or 307 only when the move is temporary. For migrations, build an explicit old→new URL map before writing rules, point each old URL directly to its final destination, update the new URL's self-canonical/internal links/sitemap/hreflang, and block release if the map creates chains, loops, irrelevant many-to-one mappings or non-200 final targets. A Search Console 'Page with redirect' state can be expected; a 'Redirect error' is a different condition that requires diagnosis.
Google treats permanent server-side redirects as a signal that the target should become canonical.
Use temporary semantics when the source URL should remain the long-term search representative.
Metricum Lab release target: every controlled old URL points to the final destination, not to another planned redirect.
Google recommends keeping migration redirects as long as possible, generally at least one year.
Status semantics
Choose the redirect code from the state of the resource, not from a folklore rule about 'SEO value'.
The useful way to think about SEO redirects is not 'which code passes the most authority?' but 'what statement is the server making about this URL?' Google currently treats 301 and 308 as permanent redirect signals and 302, 303 and 307 as temporary. For a permanent move, Google recommends a server-side permanent redirect when possible. For a genuinely temporary detour, use temporary semantics so the source can remain the long-term search representative.
| Status | Resource meaning | Request-method behavior | Search use |
|---|---|---|---|
| 301 Moved Permanently | Permanent new URI | RFC 9110 allows some clients to change POST to GET | Permanent page/domain/path move |
| 302 Found | Temporary different URI | RFC 9110 allows some clients to change POST to GET | Temporary outage, experiment or detour where source should remain primary |
| 307 Temporary Redirect | Temporary different URI | Method must be preserved | Temporary redirect for stateful/non-GET requests |
| 308 Permanent Redirect | Permanent new URI | Method must be preserved | Permanent move when method preservation matters |
Custom diagram
A decision tree separates permanent versus temporary resource moves first, then distinguishes 301/302 from method-preserving 308/307 where non-GET requests matter.
If your search query was what is 301 redirect in SEO, the precise answer is: an HTTP 301 says the resource has permanently moved and supplies a new Location. Search engines can use that as a canonicalization signal. Search demand also phrases the same task as 301 redirects SEO or seo 301 redirect; the implementation decision is still permanence plus destination equivalence, not the wording of the query.
URL-state model
A redirect retires a URL. A canonical keeps a duplicate accessible. A 404/410 says there is no replacement.
A common migration failure starts before the redirect rule: the team has not decided what the old URL means after launch. Google describes permanent redirects and rel=canonical as strong canonicalization signals, while sitemap inclusion is weaker. But those mechanisms solve different product states. If a duplicate must remain accessible—for example, a tracking or alternate presentation URL—a canonical can express preference without removing access. If the old content is retired and has a real successor, redirect it. If there is no equivalent replacement, returning 404 or 410 is more truthful than sending users and crawlers to an unrelated category or home page.
| Old URL state | Preferred control | Why | Release check |
|---|---|---|---|
| Permanent equivalent exists | 301 or 308 → equivalent final URL | Retire old address and signal new canonical location | Final destination is relevant, indexable and intended 200 |
| Temporary alternate destination | 302 or 307 | Keep source as long-term resource while routing users temporarily | Temporary condition has owner and rollback date |
| Duplicate must remain accessible | 200 + rel=canonical | Consolidate preference without removing duplicate URL | Canonical target is equivalent; signals do not conflict |
| Content deleted; no equivalent | 404 or 410 | Do not manufacture relevance with an unrelated redirect | Internal links/sitemaps stop advertising deleted URL |
Migration contract
A migration map is a reviewed data product. Regex is an implementation technique, not the source of truth.
A defensible SEO migration strategy starts with inventory, not with a wildcard. Google's current site-move documentation recommends building the URL mapping before redirects and finding important old URLs from sitemaps, server logs or analytics, Search Console link data and the CMS; it also calls out assets such as images, JavaScript and CSS where relevant. Backlink exports can add another prioritization layer because an old URL with valuable external references deserves explicit review even if it disappeared from the current navigation.
Merge crawl inventory, XML sitemaps, server logs/analytics, Search Console-linked URLs, CMS exports and high-value backlink targets. Preserve provenance so a missing URL can be explained rather than silently dropped.
Pass criterionEvery important old URL has at least one source-of-discovery field and a stable source_url key.
Mark each row as permanent move, temporary move, duplicate-kept-accessible, consolidated content, or deleted-without-replacement. Do not infer the state from URL similarity alone.
Pass criterionEvery source URL has one reviewed disposition and a reason that a product/content owner can understand.
Prefer a page that satisfies the same user task. A many-to-one consolidation is valid when content was genuinely merged, but mass redirects to an irrelevant homepage can be interpreted as soft 404 behavior.
Pass criterionEach redirect target is explainably equivalent or part of a documented consolidation.
Generate Apache, NGINX, edge or application rules from the reviewed mapping where possible. That makes the map testable before implementation and prevents a broad regex from becoming undocumented business logic.
Pass criterionA reviewer can inspect source, target, status and reason without reading server configuration.
A website migration checklist SEO teams can actually use should therefore include a mapping acceptance gate: no duplicate sources, no self-redirects, no target that is itself scheduled to redirect, no empty target for a permanent move, and no unreviewed mass consolidation. The code artifact later in this article makes those checks reproducible.
Custom diagram
Evidence sources feed an old-URL inventory, each row receives a disposition and final target, then server rules are generated and validated from the approved map.
Path integrity
Googlebot can follow long chains, but a migration you control should normally send each source directly to the final destination.
Google says Googlebot can follow up to 10 redirect hops, while its migration guidance advises redirecting directly to the final destination and, when a chain cannot be avoided, keeping it low—ideally no more than three and fewer than five. That is not a target to design toward. For controlled migrations, Metricum Lab's release target is one redirect hop: old URL → final 200 URL. Every extra hop adds latency, makes ownership harder to reason about and creates another place where a temporary status, loop or dead destination can appear.
In Screaming Frog SEO Spider, upload the planned/legacy URL list and enable the migration workflow's Always Follow Redirects option so each source can be traced to its final response.
PathMode → List; Configuration → Spider → Advanced → Always Follow Redirects
Pass criterionEvery migration source reaches the intended final status and destination; unexpected temporary hops and loops are visible.
A redirect can be correct for an old external URL while still being unnecessary in current navigation. In the crawl, inspect Response Codes → Redirection (3XX), then the Inlinks view to find pages that still link to the redirect source.
PathResponse Codes → Redirection (3XX) → Inlinks
Pass criterionCurrent internal links point directly to canonical final URLs unless a deliberate exception is documented.
Use the dedicated redirect-chain report for internal chains/loops, and the migration All Redirects report for source-to-final verification. Assign the defect to the owning rule or internal-link source rather than merely counting hops.
PathReports → Redirects → Redirect Chains
Pass criterionNo controlled source depends on another planned redirect and no loop remains.
Signal convergence
Canonicalization becomes harder to debug when each system names a different preferred URL.
The important canonical tags SEO lesson during a migration is not to add more canonical tags; it is to remove contradictions. Google's canonical documentation calls redirects and rel=canonical strong signals and sitemap inclusion a weaker signal, and says those methods can stack. It also recommends self-referencing canonicals on canonical pages and consistent internal linking to the canonical URL. During a migration, that means the new page should not redirect from the old URL while its canonical, sitemap entry, hreflang or primary internal links still point backward.
Custom diagram
An old URL permanently redirects to the final 200 URL while the final page self-canonical, sitemap, hreflang and internal links also point to that same URL.
| Layer | Expected state | Failure pattern | Fix owner |
|---|---|---|---|
| Redirect | Old URL → final new URL | Old → intermediate → final; wrong locale/category | Routing/platform |
| rel=canonical | Final URL self-canonical | Final page canonicals back to old URL or another variant | Template/SEO |
| Internal links | Link directly to final canonical URL | Navigation/body links still hit 3xx | Frontend/content |
| XML sitemap | Contains final canonical URLs | Old redirecting URLs remain submitted as current canonicals | SEO/platform |
| hreflang | Uses new reciprocal URLs | Old/redirecting URLs remain in language cluster | International SEO/platform |
Google may still select a different canonical when its systems see stronger or conflicting evidence; a user-declared canonical is not an absolute command. That is why migration validation should inspect the whole signal stack rather than conclude 'the canonical tag is correct, so the migration is correct.' The Technical SEO Audit Checklist covers this consistency at audit breadth; here it is treated as a migration release contract.
Release gate
Static preflight can catch duplicate sources, planned chains, cycles and invalid deletion states before server configuration is deployed.
A spreadsheet review is necessary but weak at finding graph defects across thousands of rows. The following small validator treats the migration map as structured data. It deliberately supports permanent migration rows (301/308) and explicit deletions (404/410). Temporary 302/307 behavior should live in a separate operational list with an owner and rollback condition, not be silently mixed into a permanent migration map.
#!/usr/bin/env python3
"""Validate a planned redirect_map.csv before release.

Required columns:
source_url,target_url,expected_status,reason

For 301/308 rows target_url is required.
For 404/410 rows target_url must be empty.
This is a static mapping check: it does not request live URLs.
"""

import csv
import sys
from pathlib import Path
from urllib.parse import urlparse

REDIRECT_STATUSES = {301, 308}
DELETION_STATUSES = {404, 410}
ALLOWED_STATUSES = REDIRECT_STATUSES | DELETION_STATUSES
REQUIRED_COLUMNS = {"source_url", "target_url", "expected_status", "reason"}


def absolute_http_url(value: str) -> bool:
    parsed = urlparse(value)
    return parsed.scheme in {"http", "https"} and bool(parsed.netloc)


def load_rows(path: Path):
    with path.open(newline="", encoding="utf-8-sig") as handle:
        reader = csv.DictReader(handle)
        missing = REQUIRED_COLUMNS - set(reader.fieldnames or [])
        if missing:
            raise ValueError(f"Missing columns: {', '.join(sorted(missing))}")
        return [{k: (v or "").strip() for k, v in row.items()} for row in reader]


def validate(rows):
    errors = []
    warnings = []
    by_source = {}

    for number, row in enumerate(rows, start=2):
        source = row["source_url"]
        target = row["target_url"]
        reason = row["reason"]
        try:
            status = int(row["expected_status"])
        except ValueError:
            errors.append(f"row {number}: expected_status must be an integer")
            continue

        if not absolute_http_url(source):
            errors.append(f"row {number}: invalid source_url {source!r}")
        if source in by_source:
            errors.append(f"row {number}: duplicate source_url {source}")
        by_source[source] = {**row, "status": status, "row": number}

        if status not in ALLOWED_STATUSES:
            errors.append(f"row {number}: status {status} is outside the release contract")
        if not reason:
            errors.append(f"row {number}: reason is required for reviewability")

        if status in REDIRECT_STATUSES:
            if not absolute_http_url(target):
                errors.append(f"row {number}: 301/308 requires an absolute target_url")
            if source == target:
                errors.append(f"row {number}: self-redirect {source}")
        elif status in DELETION_STATUSES and target:
            errors.append(f"row {number}: 404/410 row must not have target_url")

    # The planned map should point directly to final destinations.
    # If a target is also a redirect source, the release would create a chain.
    for source, row in by_source.items():
        if row["status"] not in REDIRECT_STATUSES:
            continue
        target = row["target_url"]
        if target in by_source and by_source[target]["status"] in REDIRECT_STATUSES:
            errors.append(f"planned chain: {source} -> {target} -> {by_source[target]['target_url']}")

    # Independent cycle detection produces a clearer error for A -> B -> A.
    for source in by_source:
        seen = []
        current = source
        while current in by_source and by_source[current]["status"] in REDIRECT_STATUSES:
            if current in seen:
                cycle = seen[seen.index(current):] + [current]
                errors.append("redirect cycle: " + " -> ".join(cycle))
                break
            seen.append(current)
            current = by_source[current]["target_url"]

    # Many-to-one is valid for real consolidation, but it deserves review.
    targets = {}
    for source, row in by_source.items():
        if row["status"] in REDIRECT_STATUSES:
            targets.setdefault(row["target_url"], []).append(source)
    for target, source_list in targets.items():
        if len(source_list) >= 3:
            warnings.append(f"review consolidation: {len(source_list)} sources -> {target}")

    return sorted(set(errors)), sorted(set(warnings))


def main():
    path = Path(sys.argv[1] if len(sys.argv) > 1 else "redirect_map.csv")
    rows = load_rows(path)
    errors, warnings = validate(rows)
    for warning in warnings:
        print("WARN:", warning)
    if errors:
        for error in errors:
            print("ERROR:", error)
        print(f"FAIL: {len(errors)} release-blocking mapping issue(s)")
        raise SystemExit(1)
    print(f"PASS: {len(rows)} mapping row(s); no planned chains, cycles or schema violations")


if __name__ == "__main__":
    main()
Executed with Python 3 on 2026-09-04 against synthetic valid and deliberately broken fixtures. It validates mapping structure only; it does not make network requests or prove that live targets return 200.
Use the four required columns exactly: source_url, target_url, expected_status, reason. Keep content-equivalence reasoning in the map so a reviewer can challenge questionable many-to-one mappings.
Pass criterionThe CSV is versioned with the migration release and every row has an accountable reason.
Execute python validate_redirect_map.py redirect_map.csv. Treat FAIL as a release blocker; review WARN consolidations rather than automatically rejecting them.
Pathpython validate_redirect_map.py redirect_map.csv
Pass criterionThe script exits 0 with PASS and no planned chain/cycle/schema error.
Static mapping validation cannot prove HTTP behavior. After rules are deployed, verify response status, Location header, hop count and final response with a crawler, URL Inspection for representative Google-facing URLs, or command-line checks.
Pass criterionObserved HTTP paths match the approved mapping and final pages satisfy the intended indexability/canonical contract.
For Apache, the official documentation shows server-side permanent redirects with Redirect permanent or an R=301 rewrite where appropriate; NGINX return supports 301/302/303/307/308 and its rewrite ... permanent flag returns 301. Generate configuration to match your actual server topology rather than copying a generic rule around proxies, locale routing or application state.
Observed evidence
HTTP correctness, canonical/index state and migration progress have different evidence sources and different timelines.
Custom diagram
The approved mapping is deployed, checked via HTTP crawl and logs, reviewed in Search Console and traffic data, then anomalies return to the owning mapping or template rule.
Search Console's labels matter here. Page with redirect describes a non-canonical URL that redirects and therefore is not indexed; if that is your intended legacy URL state, it is not automatically a defect to 'validate away.' Redirect error is different: Google lists conditions such as an overly long chain, a loop, a URL that grows beyond limits, or a bad/empty URL in the chain. The live URL Inspection test follows redirects and tests the final URL, although it does not display every hop.
Re-crawl the saved old-URL list and compare observed start status, hop count, final address and final status against the approved map. Do this before interpreting Search Console or traffic changes.
Pass criterionRepresentative and high-value old URLs resolve directly to the intended final destination with the intended permanent status.
Crawl the new site for self-canonical, indexability, internal links, sitemap and hreflang. Use URL Inspection on representative/high-value final URLs when Google-selected canonical evidence matters.
Pass criterionThe final page is the version the site consistently advertises as canonical; unexpected canonical selection becomes a separate diagnosis.
Track crawling/error logs, Search Console indexing/search performance, analytics and new-sitemap processing. Google notes that significant moves can fluctuate while recrawling and reindexing proceeds and may take weeks or longer depending on site size and server capacity.
Pass criterionOld-URL activity declines as intended, new-URL discovery/indexing/search activity increases, and unexpected 4xx/5xx/redirect-error cohorts have owners.
Google says the tool is for domain or subdomain moves. It is not needed for HTTP→HTTPS, www↔non-www on the same domain, or path changes within the same domain.
Pass criterionThe migration runbook uses Change of Address only when the actual move is domain/subdomain scoped.
Durable policy
Redirect retention, internal-link cleanup and monitoring need explicit owners after the release window.
Google recommends keeping migration redirects as long as possible, generally at least one year, so signals from old URLs can be recrawled and reassigned; for users, it suggests considering redirects indefinitely. That does not mean preserving internal redirect debt indefinitely. Update internal links and important external/profile/ad destinations to the new URLs so normal traffic does not depend on the compatibility layer.
| Control | Owner question | Good state | Escalation |
|---|---|---|---|
| Redirect inventory | Are all legacy URLs still covered? | Known old URLs resolve according to approved map | New 404/redirect-error cohort appears |
| Internal links | Does current site still depend on redirects? | Navigation/templates/content link to final URLs | 3xx inlinks increase after releases |
| Canonical/sitemap/hreflang | Do current signals agree? | All current discovery signals name final canonical URLs | Old/alternate URLs re-enter current signals |
| Logs/Search Console | Is migration processing normally? | Crawl shifts toward new URLs; no unexpected error cluster | Old high-value URLs stop being crawled without target discovery |
| Retention | Can any redirect safely be removed? | Age + traffic/backlink/user need reviewed before retirement | Rule removed only because 'a year passed' |
For a CMS replatform, the same principles apply even when the domain does not change. A CMS migration SEO plan should preserve URL identity where possible; where paths do change, the redirect map, canonical templates, sitemap generation and internal-link components become one release surface. If indexing behavior remains unclear after HTTP validation, the Crawled — Currently Not Indexed diagnostic workflow is the better next step than repeatedly rewriting redirect rules.
Primary sources and documentation
Every changing search, browser, interface or technical-behavior claim in this guide is tied to a current primary source.
Need help diagnosing and implementing the fix?
Metricum Lab can map legacy URL states, design redirect/canonical rules, validate migration paths before launch and monitor crawl/indexation evidence after release with explicit acceptance criteria.
Explore Technical SEO services